Sympozium
A coordination layer for multi-agent AI systems on Kubernetes
Every agent runs in an isolated workload — an ephemeral Pod, or a hardware-isolated Celln microVM. Every policy is a CRD. Coordinate multi-agent workflows on Kubernetes — from single tasks and long-running conversations to coordinated teams. Multi-tenant. Horizontally scalable. Safe by design.
Sympozium decides what agents do. Where compute happens belongs to llmfit-dra; how tokens move belongs to the serving engine. See Positioning for the boundary.
Quick Install
Then deploy to your cluster and activate your first agents:
sympozium install          # deploys CRDs, controllers, built-in Ensembles, the Celln fleet on every KVM node,
                           # the model gateway and ergoz; nothing about models is asked
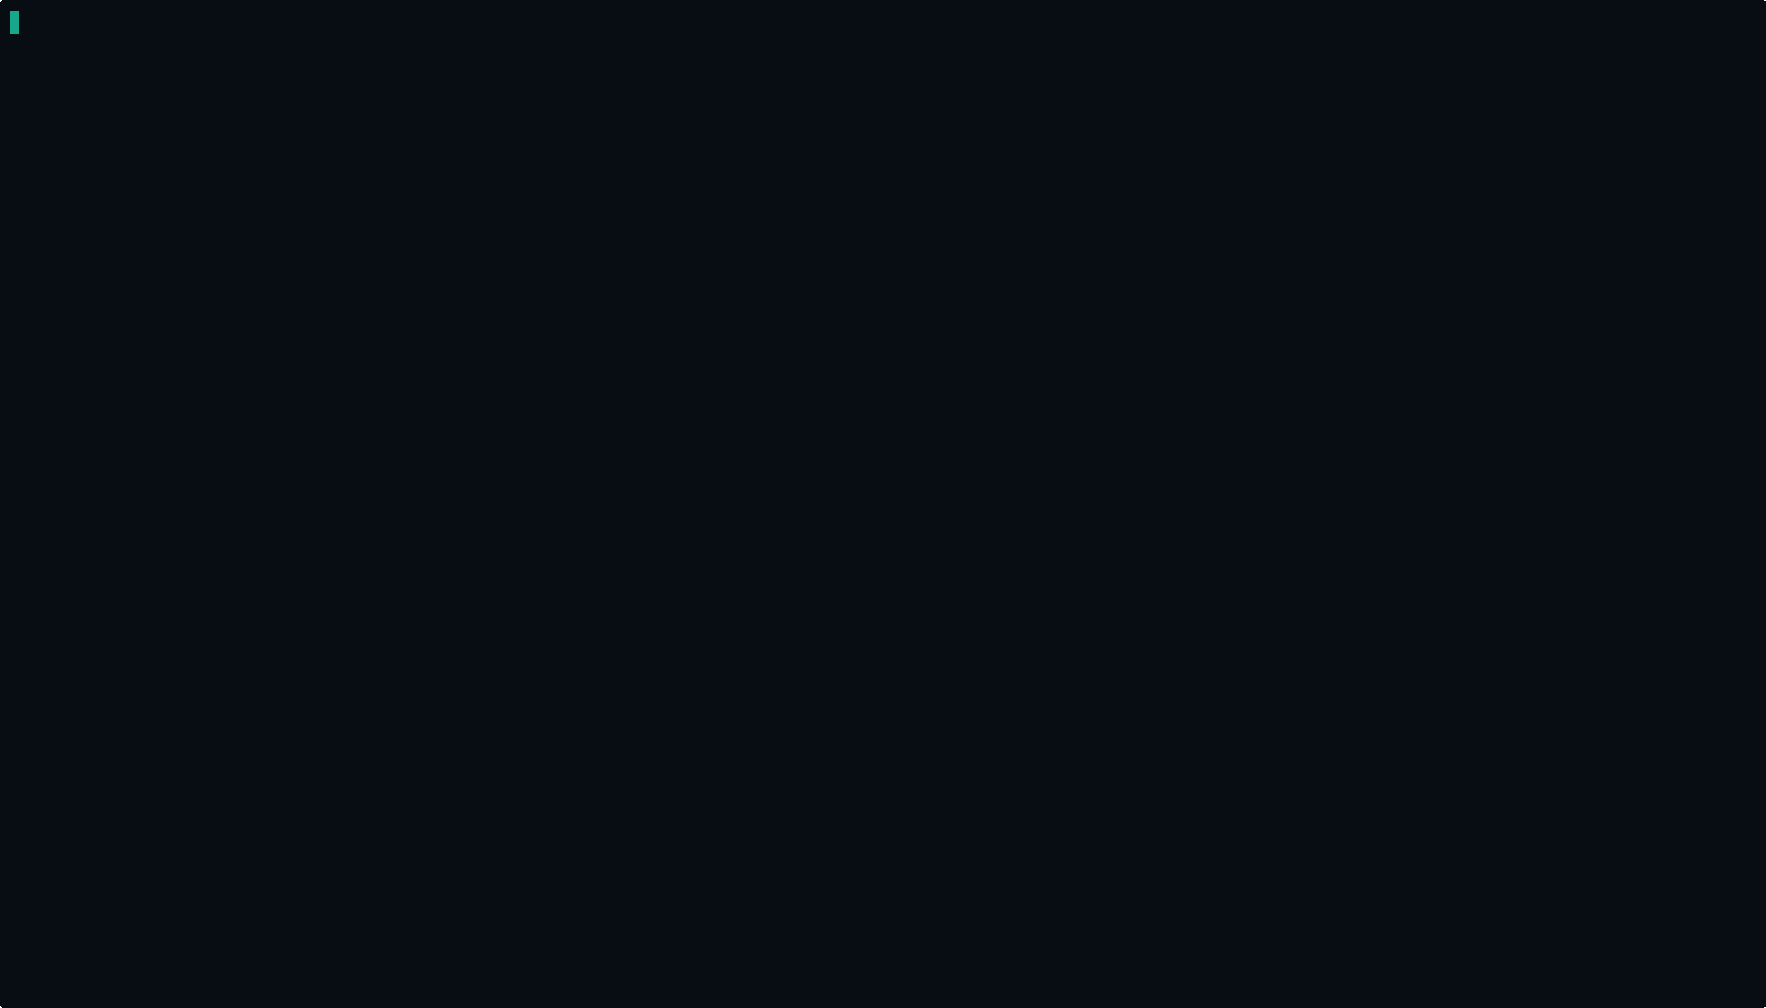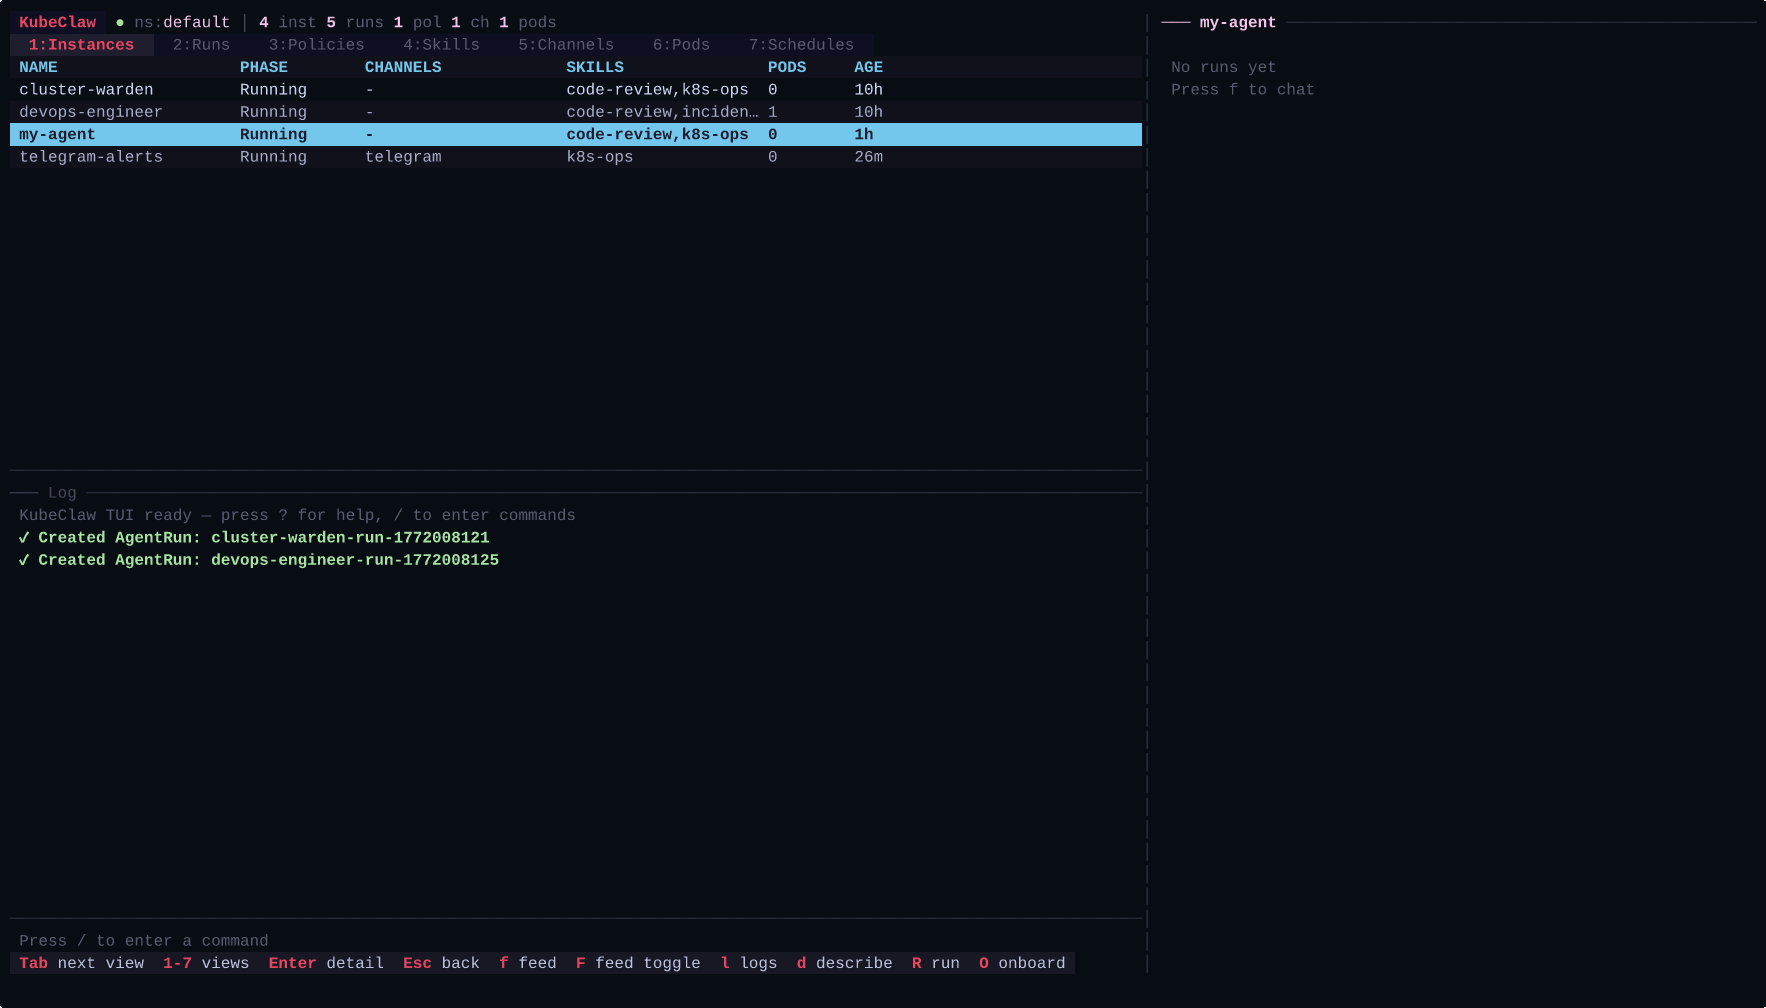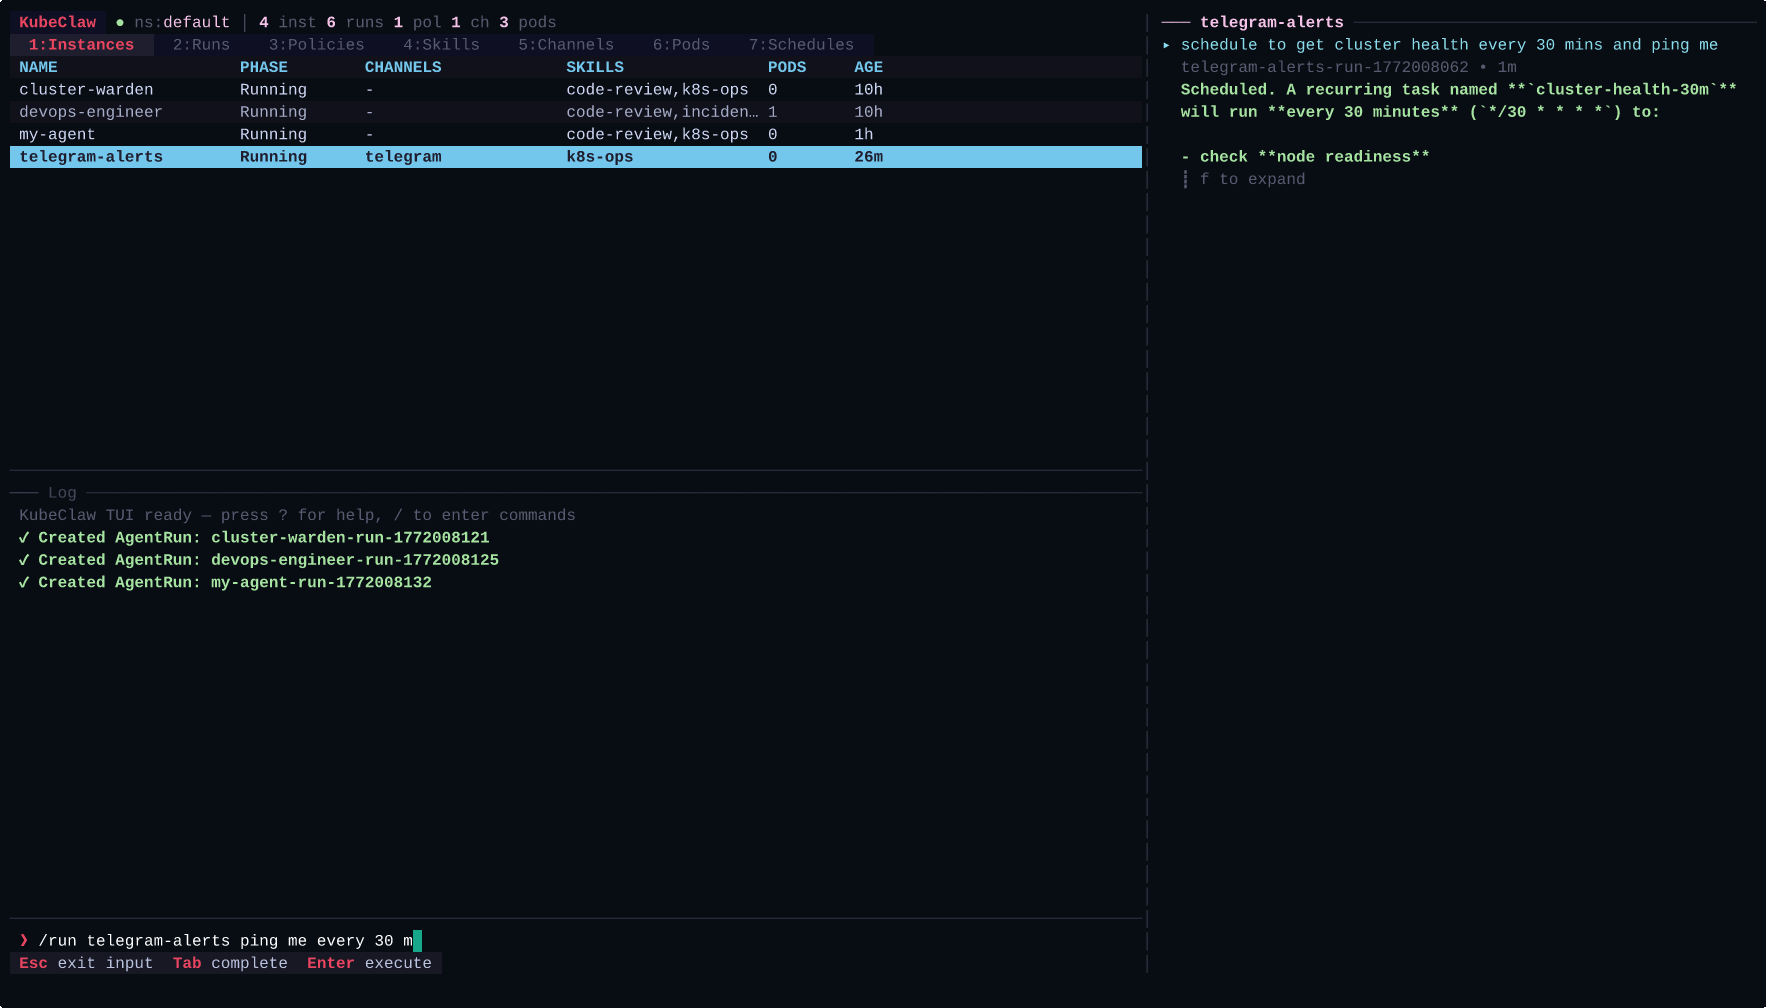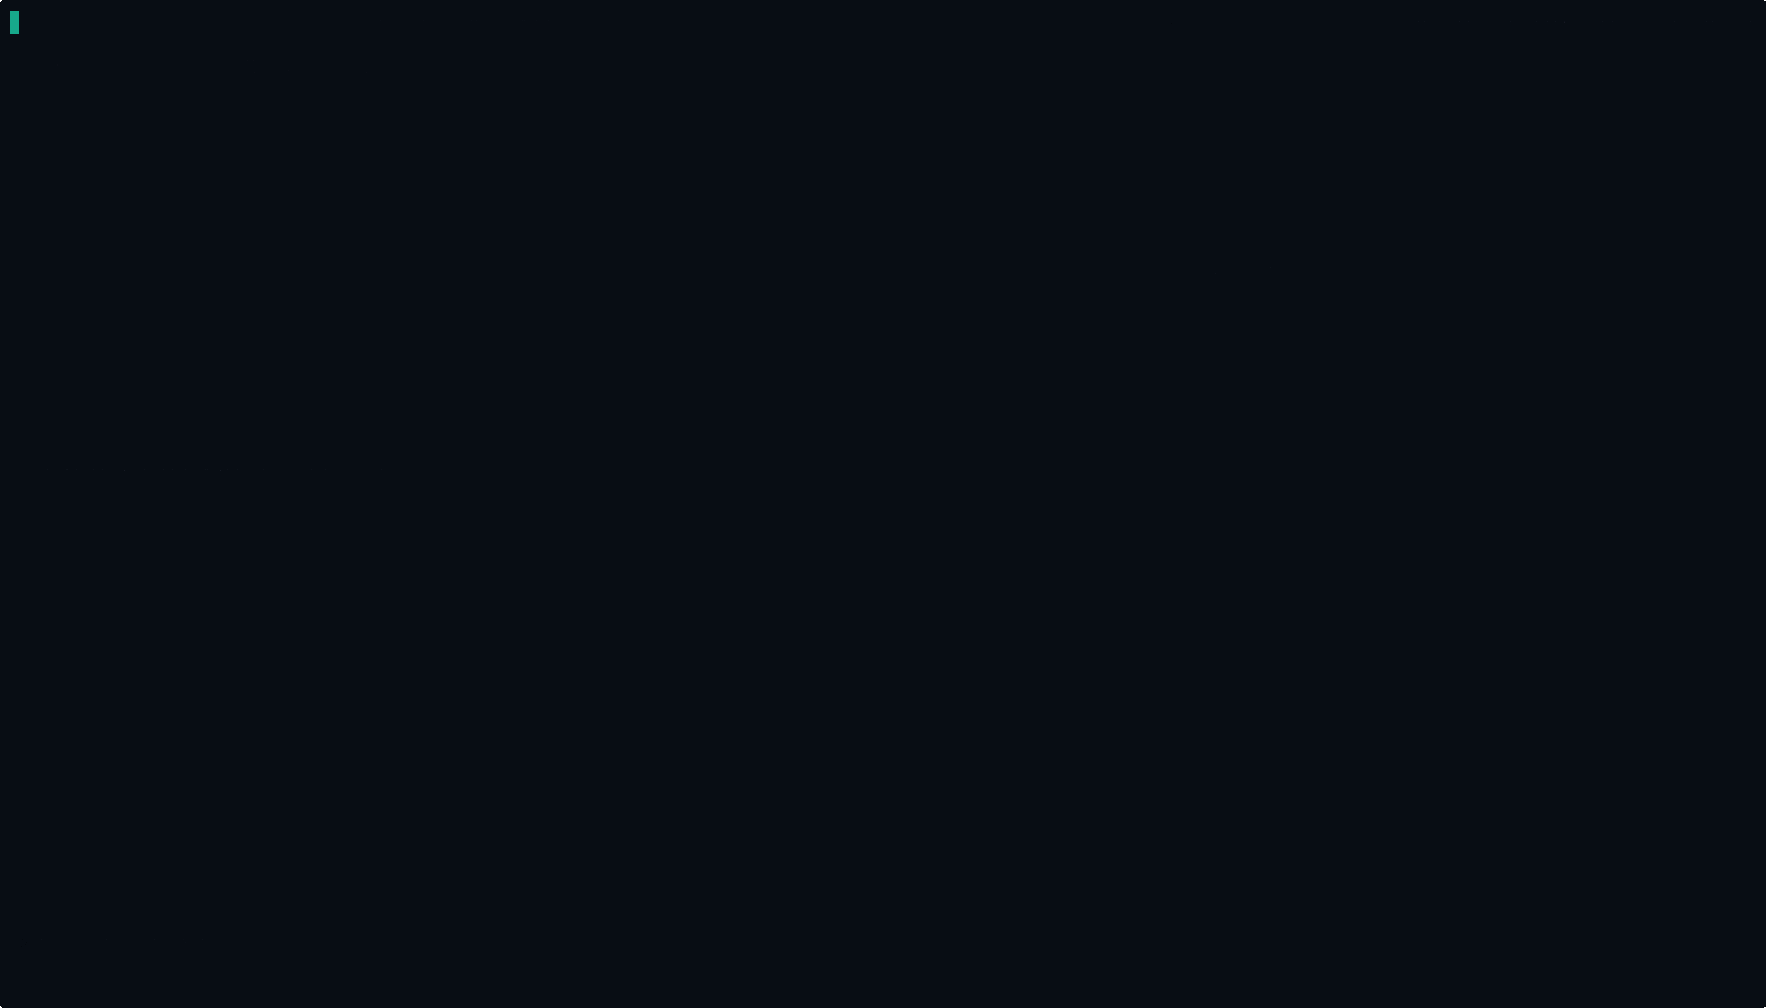
sympozium                  # launch the TUI — go to the Ensembles tab, press Enter to onboard
sympozium serve            # open the web dashboard (port-forwards to the in-cluster UI)
New here?
See the Getting Started guide — install, deploy, onboard your first agent, and learn the TUI, web UI, and CLI commands.
Why Sympozium?
Sympozium is a Kubernetes-native platform for orchestrating AI agent teams. Deploy agents for customer support, code review, data pipelines, incident response, or any domain-specific workflow — each agent gets its own pod, RBAC, and network policy with proper tenant isolation.
Bundle agents into Ensembles with delegation, sequential pipelines, and supervision relationships. Give them persistent memory, external tools via MCP servers, and cron schedules — all declared as CRDs and reconciled by controllers.
Every concept that traditional agent frameworks manage in application code, Sympozium expresses as a Kubernetes resource — declarative, reconcilable, observable, and scalable.
Key Features
- Ephemeral agent pods — each agent run is an isolated Kubernetes Job with its own security context
- Hardware-isolated agents (Celln) — one-shot and long-running agents in KVM microVMs on every labelled node; each Agent brings its own model connection and key, which a gateway adds per call and no node ever holds
- AgentHarness — run approved external harnesses (Pi, Hermes) as one-shot runs or persistent chat sessions
- Skill sidecars — every skill runs in its own container with auto-provisioned, least-privilege RBAC
- Ensembles — pre-configured bundles of agents that activate with a few keypresses
- Multiple interfaces — k9s-style TUI, full web dashboard, or CLI
- Channel integrations — Telegram, Slack, Discord, WhatsApp
- Persistent memory — agents retain context across runs via a SQLite + FTS5 memory server on a PersistentVolume
- Policy-as-CRD — feature and tool gating enforced at admission time
- OpenTelemetry — built-in observability with traces, metrics, token usage and cost estimates; accelerator power via ergoz
- Web endpoints — expose agents as OpenAI-compatible APIs and MCP servers
- Scheduled tasks — cron-based recurring agent runs
- Local inference discovery — node-probe DaemonSet discovers Ollama/vLLM/llama-cpp on host nodes with automatic model listing and node pinning
Learn More
| Topic | Description |
|---|---|
| Getting Started | Install, deploy, and onboard your first agent |
| Architecture | System design and how it all fits together |
| Custom Resources | The CRDs that model every agentic concept |
| Ensembles | Pre-configured agent bundles |
| Skills & Sidecars | Isolated tool containers with ephemeral RBAC |
| Lifecycle Hooks | PreRun and postRun containers for setup and teardown |
| Celln Backend | Hardware-isolated one-shot and enduring agents |
| Celln Fleet Installation | Install, verify, upgrade and operate the fleet; toolbox and capacity |
| Agent-bound model access | Connections, keys, origin pins and the model gateway |
| AgentHarness | Approved external harnesses and persistent chat sessions |
| Security | Defence-in-depth at every layer |
| Writing Skills | Build your own SkillPacks |
| Writing Tools | Add new tools to the agent runner |
| Model Connections | Reusable model routes for persistent Hermes and native Celln harnesses |
| Ollama & Local Inference | Node-based and in-cluster Ollama setup with auto-discovery |
| LM Studio | Local GGUF model serving with desktop GUI |
| llama-server | llama.cpp server with full GPU control and node auto-discovery |
| Unsloth | Fine-tuned models served via llama.cpp or vLLM |
| AWS Bedrock | Amazon Bedrock setup with Claude, Nova, and other foundation models |
Project Links
- GitHub Repository
- Releases
- License — MIT